A state urban development agency in India needed one reliable view of its sewage treatment plants (STPs), with a water treatment plant (WTP) module to follow. The data lived in spreadsheets, printed sheets, and separate SCADA systems at each plant. Leadership couldn't see capacity, utilisation, plant status, O&M contracts, or treated-water quality in one place.
I led the engagement as project manager and technical lead, working alongside the agency's team and the central server team. This is what we built, and what we learned in the first week.
The problem: no two plants run the same system
- Modern SCADA at some plants, with data ready to push.
- Older SCADA on outdated PCs, with no clean way to export.
- Standalone panels with readings but no network connection.
- No SCADA at all at many plants, where data lives on paper.
Any platform that assumed one data source would leave most plants out. The design had to meet each plant where it was.
Start with the governance hierarchy
Before writing code, we mapped how reporting actually works: large municipal corporations report directly to the State, while 150+ smaller municipalities report through regional zones. That structure decided the access model (State, zone, local body, plant), the dashboard drill-downs, and who acts on which alert. Getting it wrong would have meant rebuilding permissions later.
Turning paper into trusted data
We started from photos of printed sheets, then moved to the agency's master Excel file. We built an importer that cleans real-world mess: mixed date formats, values like “0.57 Cr” and “< 4.0” in lab results, and inconsistent spellings of the same plant or town. Every import reconciles exactly against the official totals.
The result was a single source of truth covering 200+ functional STPs, 6,000+ MLD of installed capacity, roughly three-quarters of it in use, plus a pipeline of plants under construction and treated-water lab samples. Reconciling to the official numbers built trust faster than any polished UI could.
A working dashboard in days
The prototype was built in React (Vite, TypeScript), Node.js and PostgreSQL. It includes:
- KPI tiles and capacity by jurisdiction.
- Operational status and the construction pipeline.
- O&M contracts nearing expiry.
- Water quality against permitted limits.
- A data-completeness check, so gaps are visible and fixed at source.
- A searchable plant register with export.
- A demo of jurisdiction-based access.
It surfaced decisions for leadership immediately: expired or soon-to-expire contracts, projects past their target date, under-utilised plants, and plants never tested for water quality.
Security from the first sprint
Government platforms must clear a VAPT (vulnerability assessment and penetration testing) audit before go-live. We designed for that from day one: server-side access control, input validation, rate limiting, security headers, an audit trail, and personal data kept out of APIs and exports. Retrofitting these at the end is slower and riskier.
Architecture
- API-first backend in Node.js, with a modular build so the WTP module, GIS map and reports can be added without rework.
- PostgreSQL + TimescaleDB for relational plant data alongside time-series SCADA readings.
- Read-only SCADA integration, so the monitoring platform can never affect plant operations.
- REST/JSON webhooks for incoming data, served behind Nginx on Ubuntu.
Integrating 200+ SCADA systems: four routes, one format
The hardest part wasn't code. It was getting hundreds of different systems to deliver the same data. We wrote an integration specification with four routes, so no plant is left behind:
- Direct push from modern SCADA to the platform's API.
- Edge gateway for older SCADA that can't push on its own.
- CSV export for legacy systems that can only produce files.
- Manual CSV entry for plants with no SCADA.
All four deliver the same standard data points. The specification also covers assumptions, data-quality rules, roles, onboarding steps, an FAQ, and a site-survey form for each plant.
Integrating 200+ different SCADA systems is a standards and people problem, not a coding problem: one data format, several ways to deliver it.
Proving the pipeline before asking anyone else to
Before asking field agencies to send data, we tested the pipeline ourselves. Working with the central server team, we diagnosed and fixed server and database issues, then completed the first successful test transmission into the central database in the agreed format. When the first municipal corporation sent formal technical queries, we answered them point by point, and its SCADA agency started the site survey for the first pilot plant.
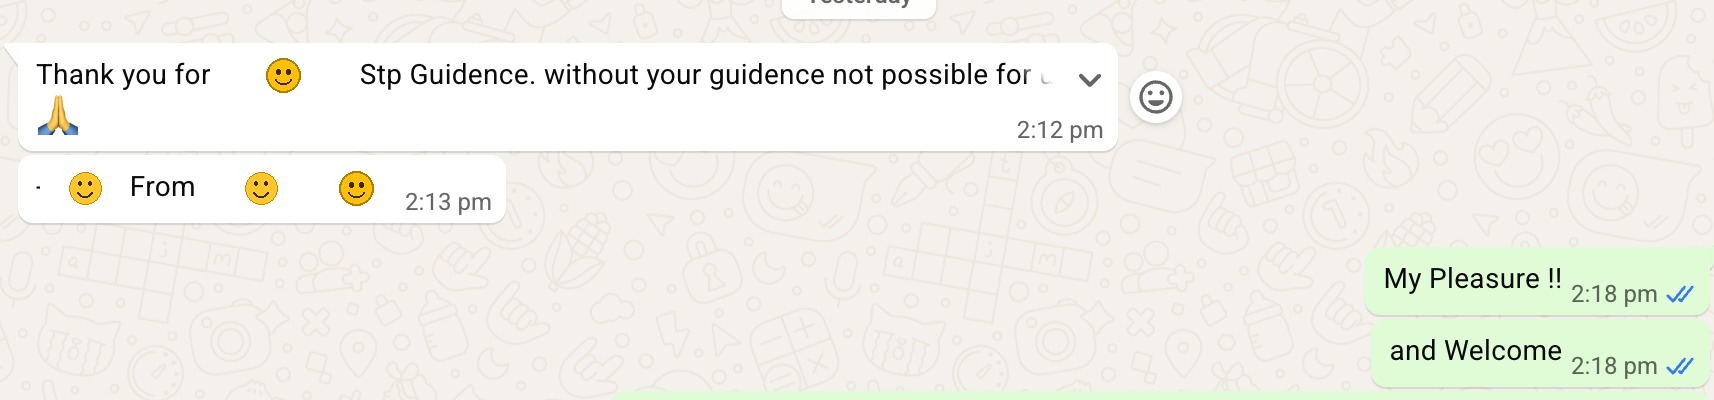
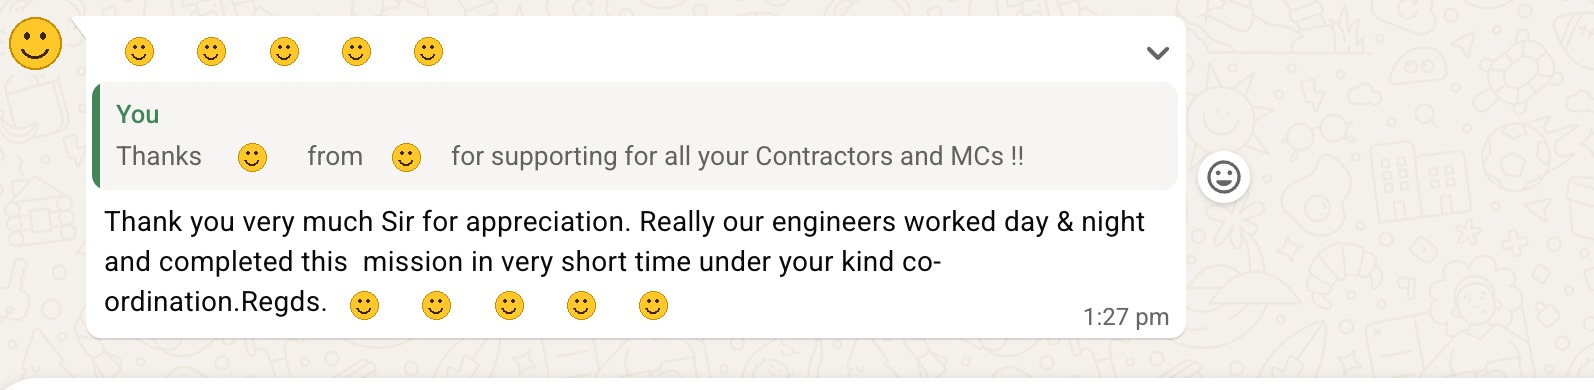
What the team said
Feedback from the people we worked with during the first weeks of the engagement:
Lessons worth reusing
- Start with the governance hierarchy. It drives access, drill-downs, and alert ownership.
- Real government data is messy. Reconcile against official totals first.
- Standardise the data format, then offer multiple ways to deliver it.
- Test your own pipeline before field agencies do.
- Design for the security audit from the first sprint, not the last.
What's next
Pilot the first plant end to end, then roll out zone by zone. After that: live SCADA dashboards (inflow, energy per million litres, alerts), role-based logins with OTP, the WTP module, a GIS map, automated MIS reports, and the VAPT audit ahead of production go-live.
Need to bring scattered plant or field data into one platform?
We build monitoring dashboards, SCADA integrations, and data platforms for infrastructure and utility teams. Talk to us directly, no agency layers.
Book a Free Consultation